Inference in any environment

Serve and scale models. Use via API, or serve in your cloud.

Trusted by Machine Learning teams from
Swiggy logo featuring its location pin icon beside the bold word 'SWIGGY' on a white background.Physics Wallah (PW) logo featuring the initials 'PW' inside a circular emblem alongside the brand name in bold text. Pixis logo in bold black lettering with a stylized 'X' on a white background. Tata 1mg logo in black on a white backgroundInVideo logo featuring a rounded abstract icon beside the lowercase word 'invideo' on a white background. Mindtickle logo in black lowercase text on a white background.Lyric logo featuring a stylized abstract icon beside the brand name 'Lyric' in bold black text.
Swiggy logo featuring its location pin icon beside the bold word 'SWIGGY' on a white background.Physics Wallah (PW) logo featuring the initials 'PW' inside a circular emblem alongside the brand name in bold text. Pixis logo in bold black lettering with a stylized 'X' on a white background. Tata 1mg logo in black on a white backgroundInVideo logo featuring a rounded abstract icon beside the lowercase word 'invideo' on a white background. Mindtickle logo in black lowercase text on a white backgroundLyric logo featuring a stylized abstract icon beside the brand name 'Lyric' in bold black text.

Trusted by Machine Learning teams from
Pay-as-you-go or Reserve for Scale
AI platform showcasing a curated library of production-ready foundation models, including DeepSeek-R1, Flux.1 Kontext, Whisper v3 Turbo, and Llama 3.1 405B, with support for more than 150 deployable AI models across language, vision, and multimodal workloads

Pay-as-you-go with model APIs

Pre-optimized GenAI models on tap. No infra setup needed.

Optimised for latency
Developer-friendly tools for usage, and tracing included.
Easy to start
100% Uptime
Check Model Library
SimpliSmart logo above a global AI infrastructure map, showing connected deployment regions across US West, US East, London, Spain, Mumbai, and Singapore, representing distributed cloud infrastructure for low-latency AI model training and inference worldwide.

Scale Seamlessly with Dedicated Clusters

Large workloads run on dedicated clusters
Sub-second cold-starts
Optimise for cost or latency, as you need
Scale based on metrics: latency, memory, concurrency
Scale-to-zero based on traffic
Launch a Cluster
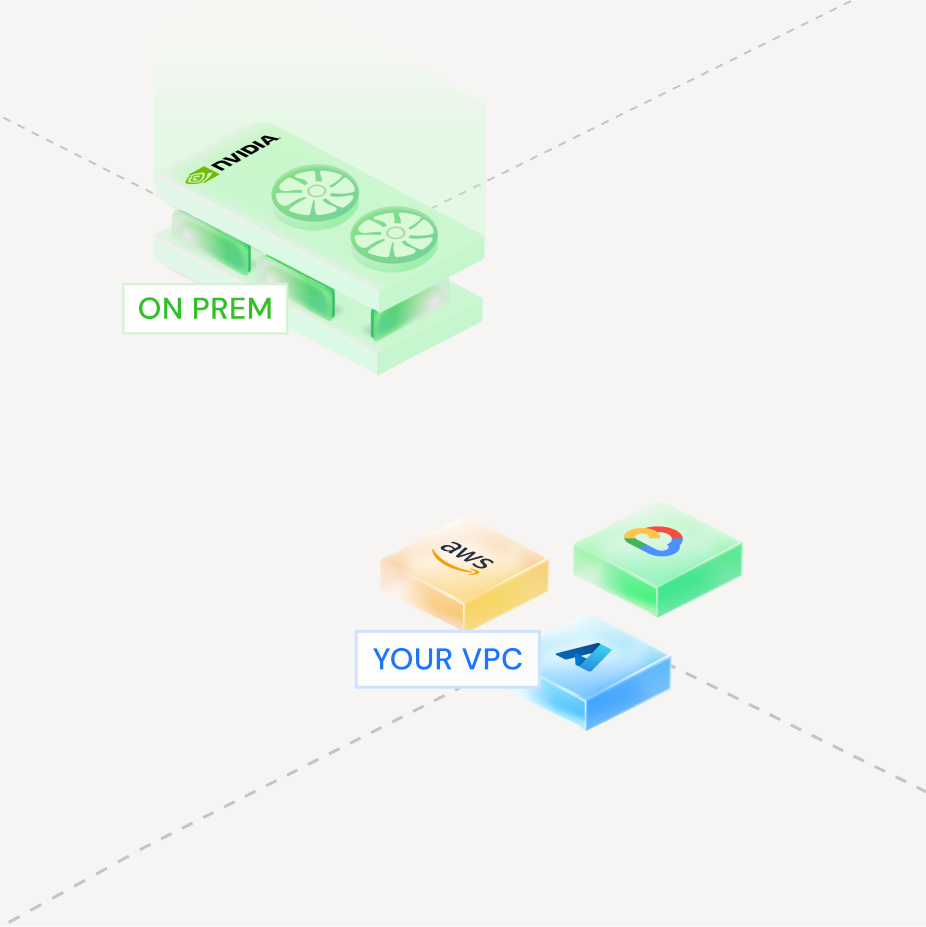
Hybrid AI deployment architecture illustrating NVIDIA on-premises GPU infrastructure alongside private cloud deployment options in AWS, Google Cloud, Microsoft Azure, and a customer VPC, enabling flexible and secure AI model deployment across on-premises and cloud environments.

Build in your cloud or on-prem

Keep models and data completely in your environment

Deploy models directly onto your Kubernetes or Slurm cluster
Deploy seamlessly in air-gapped systems
Enterprise-grade security with audit trails and network isolation
No Data Leaves Your Cloud
Check Model Library
IoT-Plattform

Pay-as-you-go or Reserve for Scale

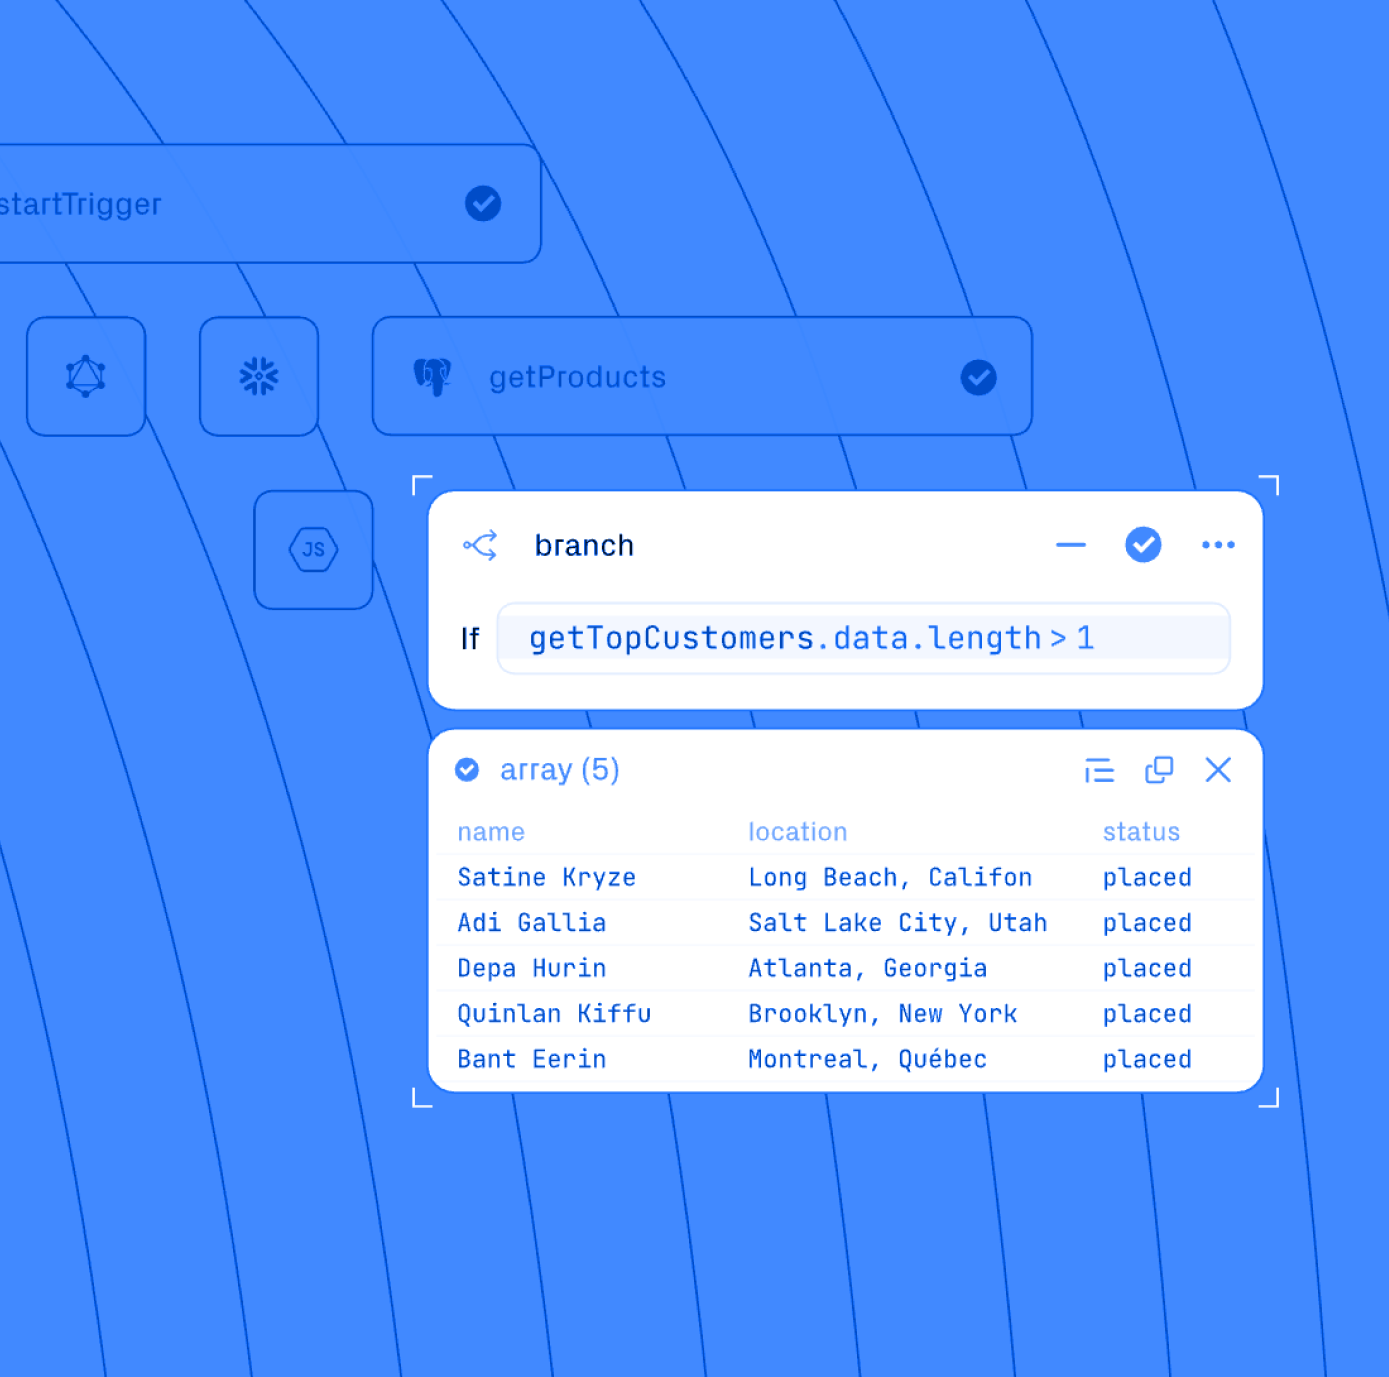
Blue illustration featuring a search interface, website data table, and abstract curved lines in the background.

Pay-as-you-go with model APIs

Pre-optimized GenAI models on tap. No infra setup needed.

Optimised for latency
Developer-friendly tools for usage, and tracing included.
Easy to start
Check Model Library
Blue illustration featuring a search interface, website data table, and abstract curved lines in the background.

Pay-as-you-go with model APIs

Pre-optimized GenAI models on tap. No infra setup needed.

Optimised for latency
Developer-friendly tools for usage, and tracing included.
Easy to start
Check Model Library

Pay-as-you-go with model APIs

Pre-optimized GenAI models on tap. No infra setup needed.

Optimised for latency
Developer-friendly tools for usage, and tracing included.
Easy to start
Check Model Library

Pay-as-you-go with model APIs

Pre-optimized GenAI models on tap. No infra setup needed.

Optimised for latency
Developer-friendly tools for usage, and tracing included.
Easy to start
Check Model Library

Hear from our Partners

Don't take just our word for it, hear from companies that Simplismart has partnered with
"With Simplismart, we trained and deployed a vision model to process medical prescriptions at 95% accuracy. Their fine-tuning made inference fast, efficient, and effortlessly scalable"

Bhaskar Arun

Lead Data Scientist, Tata 1mg

"Running workloads at our scale demands both speed and adaptability. Simplismart delivered the fastest infrastructure we’ve used and stayed on top of every new development to keep us ahead.”

Ajay Dubey

Senior Engineering Manager, Mindtickle

"Simplismart’s optimizations cut our image generation costs from $30,000 to under $1,000 while halving inference time. Their solution integrated seamlessly, scaling effortlessly with our growing demand."

Shivam R.

Senior Director of Engineering, Invideo

"Simplismart’s solutioning helped us transition to custom models, and their fine-tuning expertise boosted our accuracy. The support quality has been outstanding and they handle all the MLOps heavy lifting so we can focus on building"

Elad Hirsch

Founding Research Scientist, Lica

"We had invested in GPUs, and Simplismart proved the best way to maximize them. Their optimizations cut our peak GPU usage from 15 to 6 while meeting latency targets, making our infrastructure faster and more cost-efficient"

Soumyadeep Mukherjee

Co-Founder & CTO, Dashtoon

Find out what is tailor-made inference for you.