Deploy and scale

Llama
Whisper
Flux
Deepseek
Llama

Inference that adapts to your needs
Tata 1mg logo in black on a white background. Telus logo in black on a white backgroundSanas logo featuring a geometric black icon beside the word 'sanas' on a white background. Mindtickle logo in black lowercase text on a white background. EMA logo featuring a circular black icon beside the bold text 'Ema' on a white background.Swiggy logo featuring its location pin icon beside the bold word 'SWIGGY' on a white background.InVideo logo featuring a rounded abstract icon beside the lowercase word 'invideo' on a white backgroundPixis logo in bold black lettering with a stylized 'X' on a white background.Physics Wallah (PW) logo featuring the initials 'PW' inside a circular emblem alongside the brand name in bold text. Lyric logo featuring a stylized abstract icon beside the brand name 'Lyric' in bold black text.
Tata 1mg logo in black on a white background. Sanas logo featuring a geometric black icon beside the word 'sanas' on a white background. Mindtickle logo in black lowercase text on a white background. EMA logo featuring a circular black icon beside the bold text 'Ema' on a white background.Swiggy logo featuring its location pin icon beside the bold word 'SWIGGY' on a white background.InVideo logo featuring a rounded abstract icon beside the lowercase word 'invideo' on a white background. Pixis logo in bold black lettering with a stylized 'X' on a white background.Physics Wallah (PW) logo featuring the initials 'PW' inside a circular emblem alongside the brand name in bold text. Lyric logo featuring a stylized abstract icon beside the brand name 'Lyric' in bold black text.
HeyGen logo with geometric four-point icon Higgsfield logo with abstract wave icon Tata 1mg logo in black on a white background. Apna logo featuring the brand name 'apna' in bold lowercase black lettering. Sanas logo featuring a geometric black icon beside the word 'sanas' on a white background.Yubi company logo with stylized black and gray Y icon Shiprocket logo with stylized triangular delivery iconMindtickle logo in black lowercase text on a white background.EMA logo featuring a circular black icon beside the bold text 'Ema' on a white background. Swiggy logo featuring its location pin icon beside the bold word 'SWIGGY' on a white background.InVideo logo featuring a rounded abstract icon beside the lowercase word 'invideo' on a white background. Physics Wallah (PW) logo featuring the initials 'PW' inside a circular emblem alongside the brand name in bold text. Pixis logo in bold black lettering with a stylized 'X' on a white background.Lyric logo featuring a stylized abstract icon beside the brand name 'Lyric' in bold black text.

Tailor-made inference for any model at scale

Model Library

Pick from 150+ open-source models or import custom weights

Blue check mark icon indicating verification or confirmation.

Get started quickly and pay-as-you-go

Blue checkmark icon indicating verification or correctness.

Import custom models from 10+ cloud repositories

Blue check mark symbol indicating confirmation or verification.

Supports LLMs, VLMs, Diffusion and Speech models

Get Started
Deploy Now

Deploy in our cloud or yours

Blue checkmark icon on a transparent background.

Deploy in any private VPC or on-prem setup


Blue checkmark icon on a transparent background.

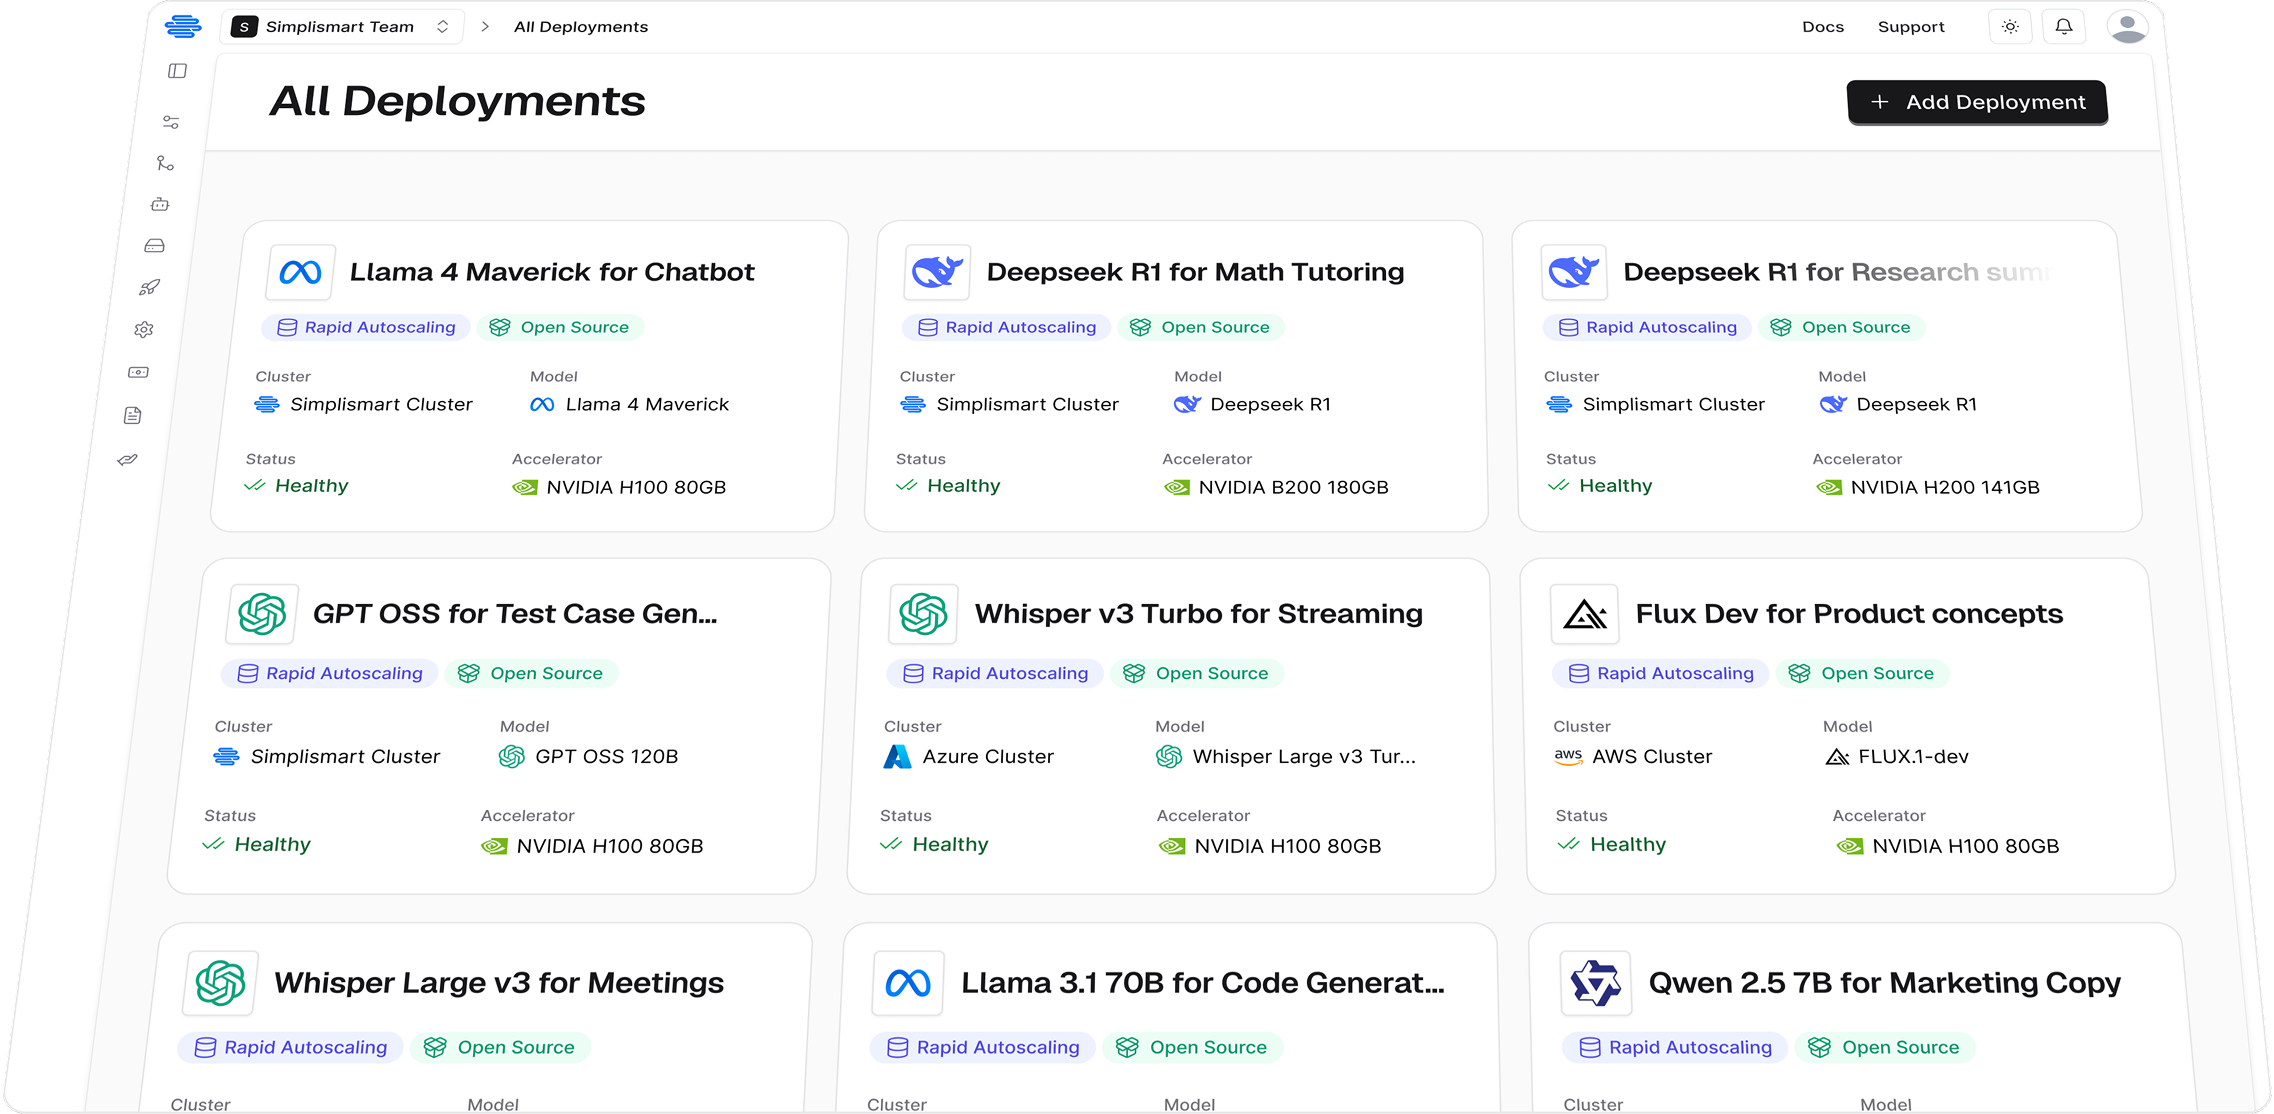
One control plane to manage deployments across clouds

Blue check mark symbol.

Native integration with 15+ clouds

Blue tick mark

B200s, H100s, A100s, L40S, A10G available across the globe

Get Started
Our paper on Autoscaling

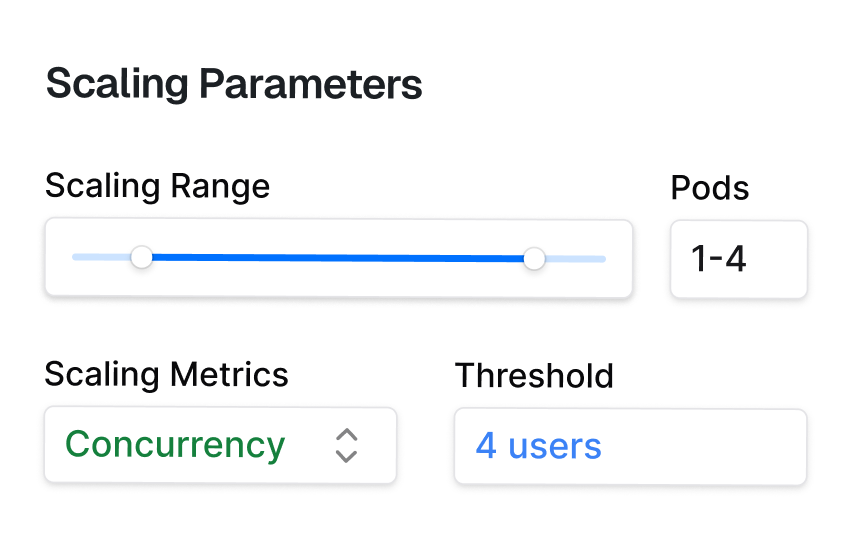
Scale up in less than 500ms

Blue check mark symbol indicating verification or approval.

Rapid auto-scaling for spiky traffic

Blue checkmark symbol indicating verification or confirmation.

Scale based on specific metrics to serve strict SLAs

Blue checkmark icon indicating verification or confirmation.

Scale-to-zero based on traffic

Get Started
Modular inference stack

Built for performant runtime

Blue check mark icon indicating verification or approval.

Custom built CUDA kernels

Blue check mark icon indicating verification or approval.

Get lowest TTFT and E2E latency

Blue check mark icon indicating verification or approval.

or maximize throughput with most affordable costs

Table highlighting various LLM inference optimization techniques, including speculative decoding, KV caching, CUDA graphs, prefix caching, tensor parallelism, Flash Attention, paged attention, and function calling.
Get Started

The most common
mistake in inference

One size does not fit all
Your product deserves tailor-made inference, not generic APIs
Voice Agents
Optimised for Latency < 100ms,
Streaming STT + TTS
Scale based on latency
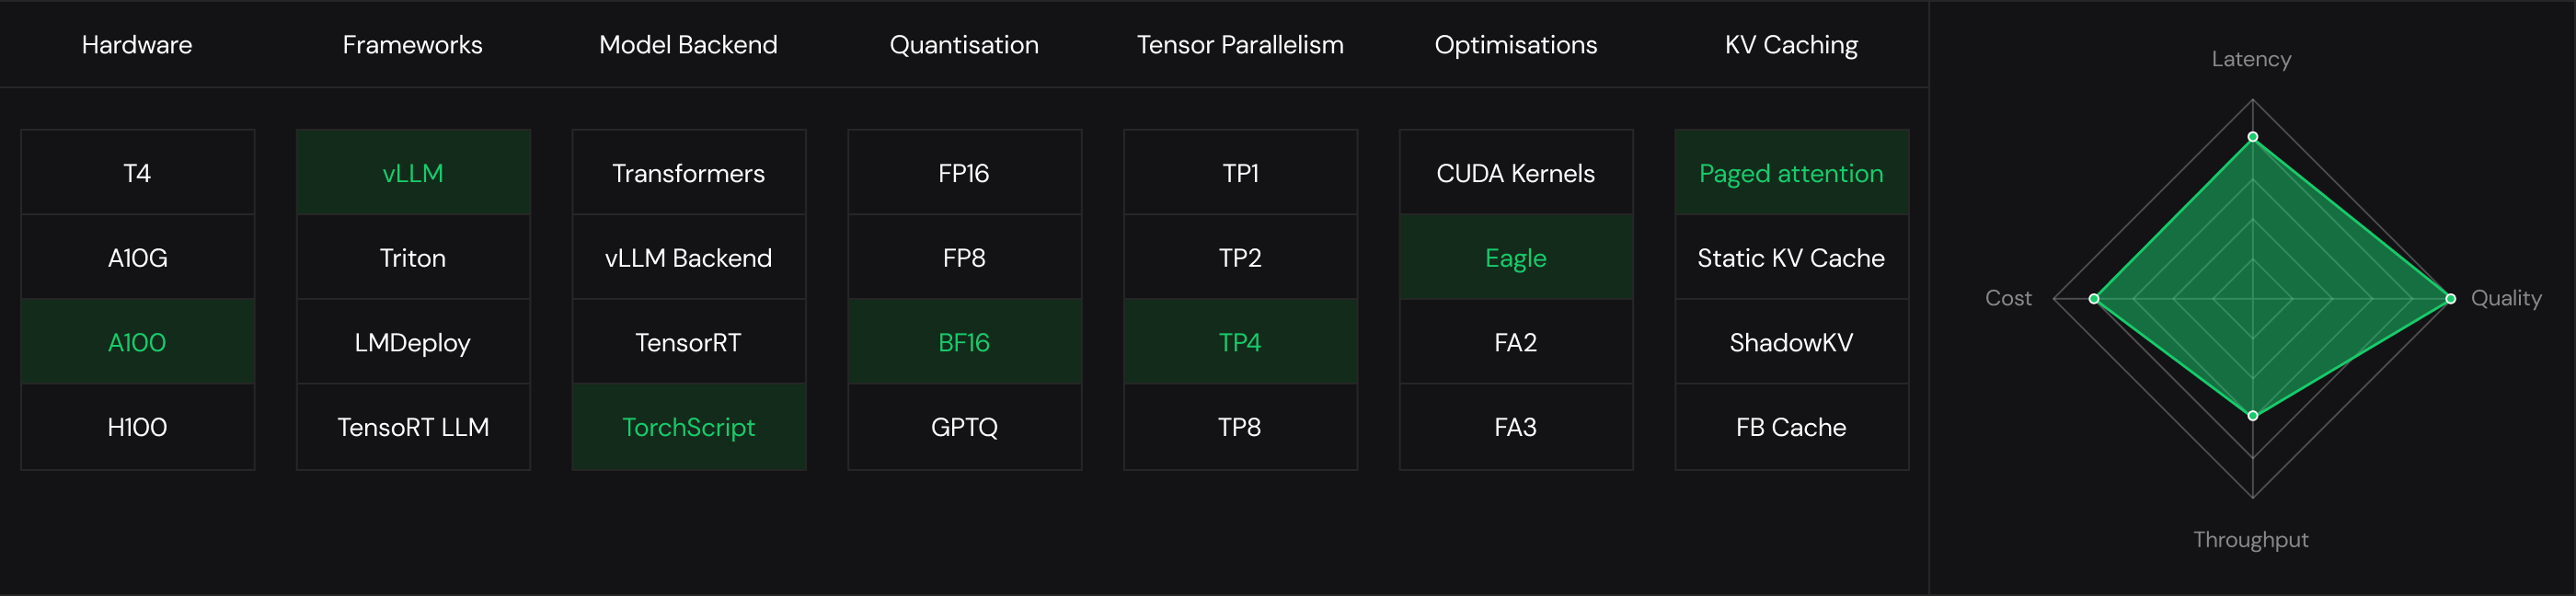
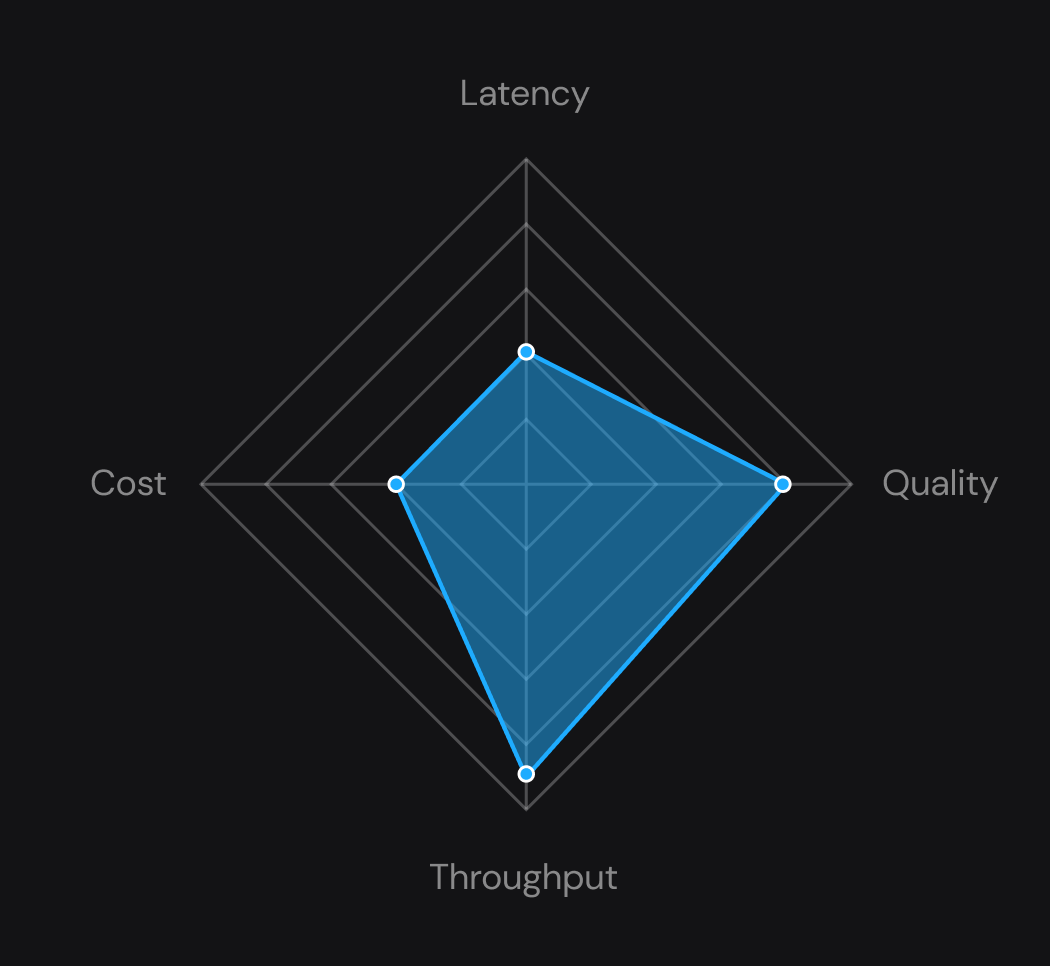
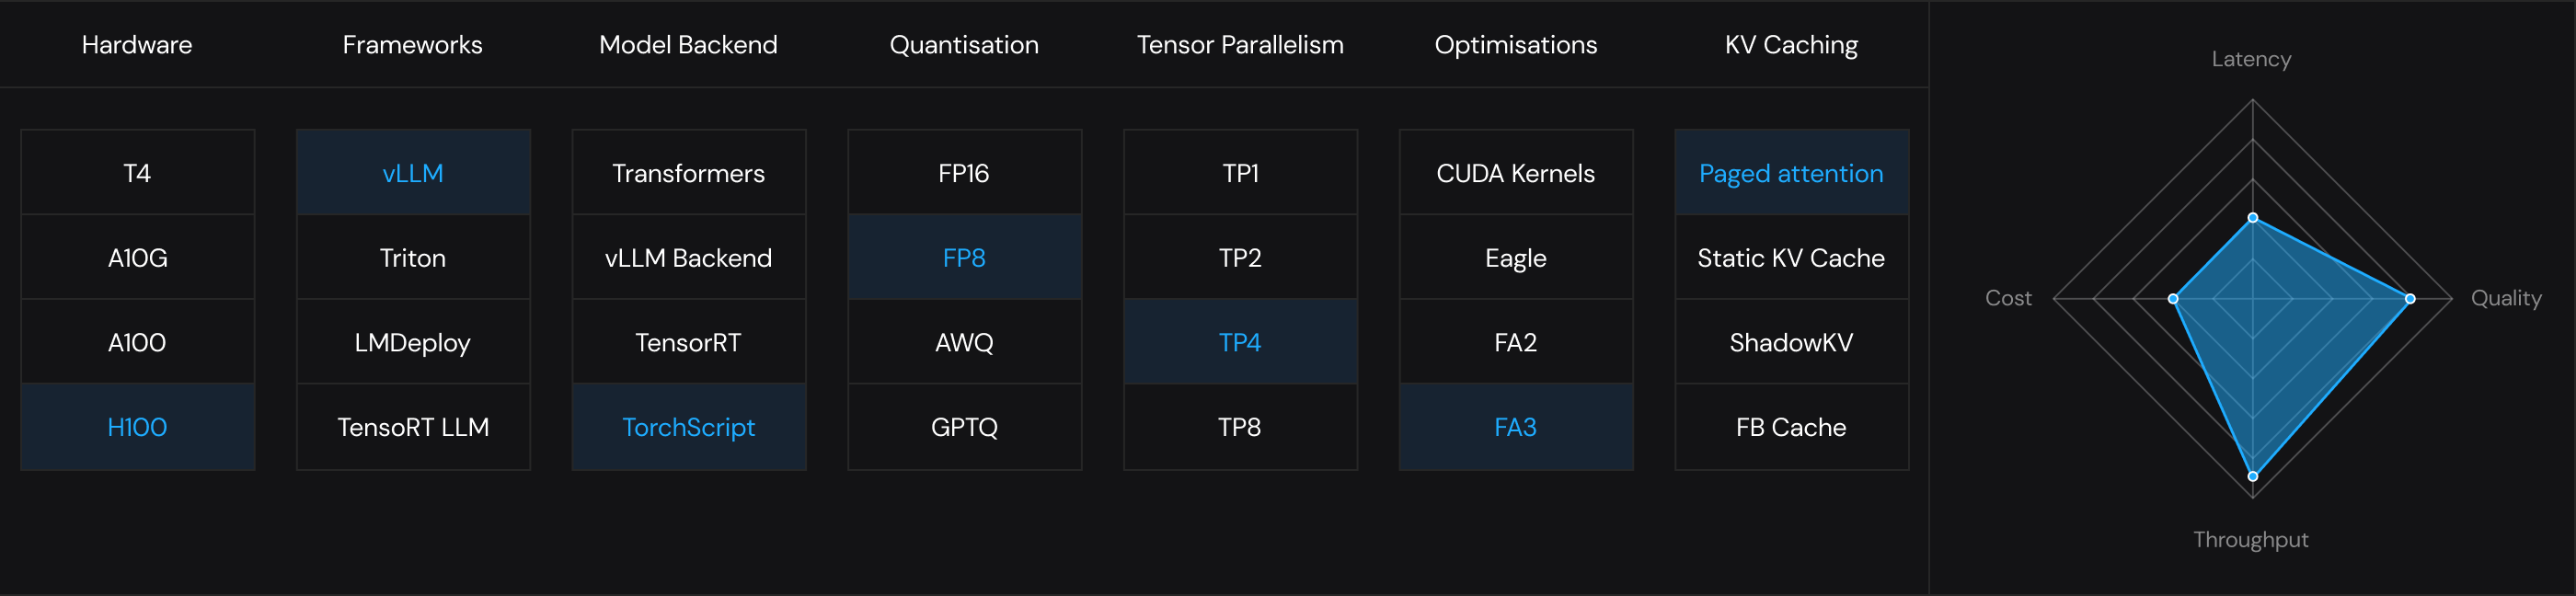
AI inference configuration dashboard showing hardware, framework, model backend, quantization, tensor parallelism, optimization, and KV caching options with a performance comparison chart for latency, quality, throughput, and cost
Document processing
Optimized for high throughput
VLM/LLM
Scale based on concurrency
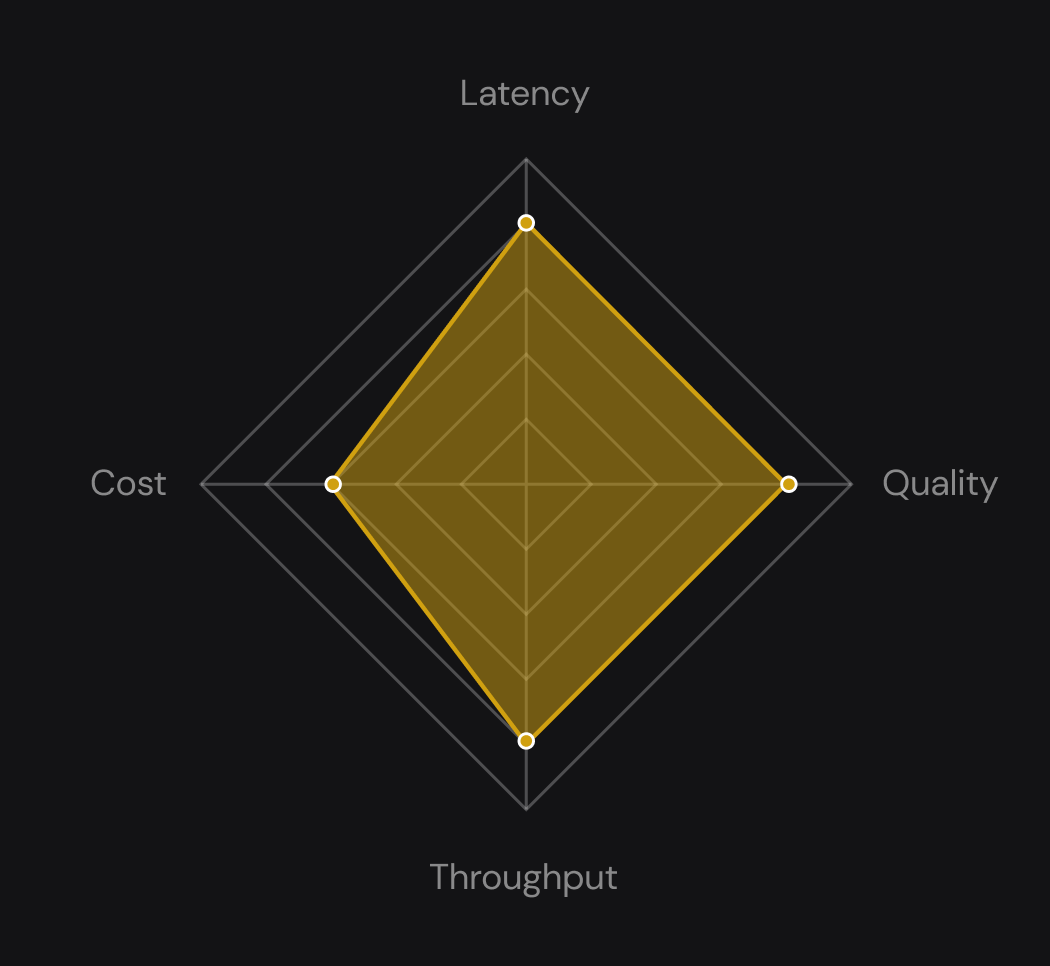
AI inference optimization dashboard with configurable hardware, framework, model backend, quantization, tensor parallelism, optimization, and KV caching settings, alongside a performance chart comparing latency, quality, throughput, and cost
Content Generation
Optimised for Cost
Fine-tuned LLM
Scale based on usage
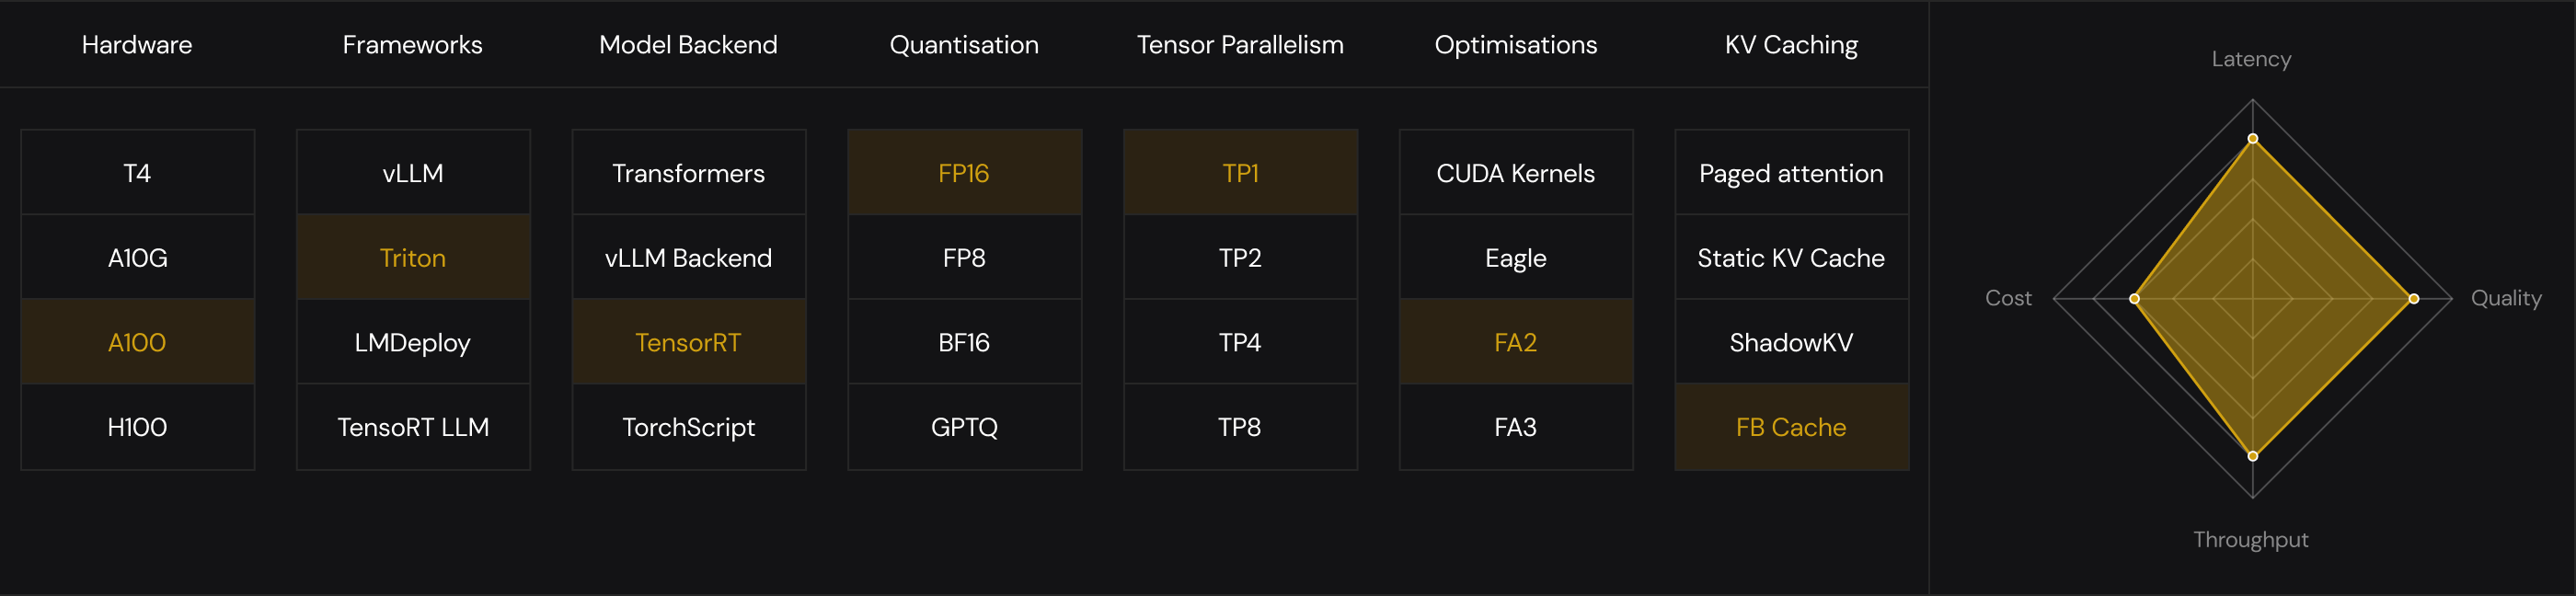
AI inference optimization dashboard with configurable hardware, framework, model backend, quantization, tensor parallelism, optimization, and KV caching settings, featuring a performance chart comparing latency, quality, throughput, and cost for the selected configuration
Real-time multi-agent reasoning
Voice Agents
Real-time multi-agent reasoning
Streaming STT + TTS
Real-time multi-agent reasoning
TTFB <100ms
Real-time multi-agent reasoning
Scale based on latency threshold
Hardware
Frameworks
Model Backend
Quantisation
Model Backend
Optimisations
KV Caching
T4
vLLM
Transformers
fp16
TP1
CUDA Kernels
Paged attention
A10G
Triton
vLLM Backend
FP8
TP2
Eagle
Static KV Cache
A100
LMDeploy
TensorRT
AWQ
TP4
FA2
ShadowKV
H100
Static KV Cache
ShadowKV
ShadowKV
ShadowKV
ShadowKV
FB Cache
Dark-themed LLM inference stack showing hardware, frameworks, backends, quantization, optimizations, KV caching, and performance metrics.
Radar chart comparing LLM performance across latency, quality, throughput, and cost.
Real-time multi-agent reasoning
Document processing
Real-time multi-agent reasoning
Optimized for high throughput
Real-time multi-agent reasoning
VLM/LLM
Real-time multi-agent reasoning
Scale based on concurrency
Hardware
Frameworks
Model Backend
Quantisation
Model Backend
Optimisations
KV Caching
T4
vLLM
Transformers
fp16
TP1
CUDA Kernels
Paged attention
A10G
Triton
vLLM Backend
FP8
TP2
Eagle
Static KV Cache
A100
LMDeploy
TensorRT
BF16
TP4
FA2
ShadowKV
H100
TensoRT LLM
ShadowKV
GPTQ
TP8
FA3
FB Cache
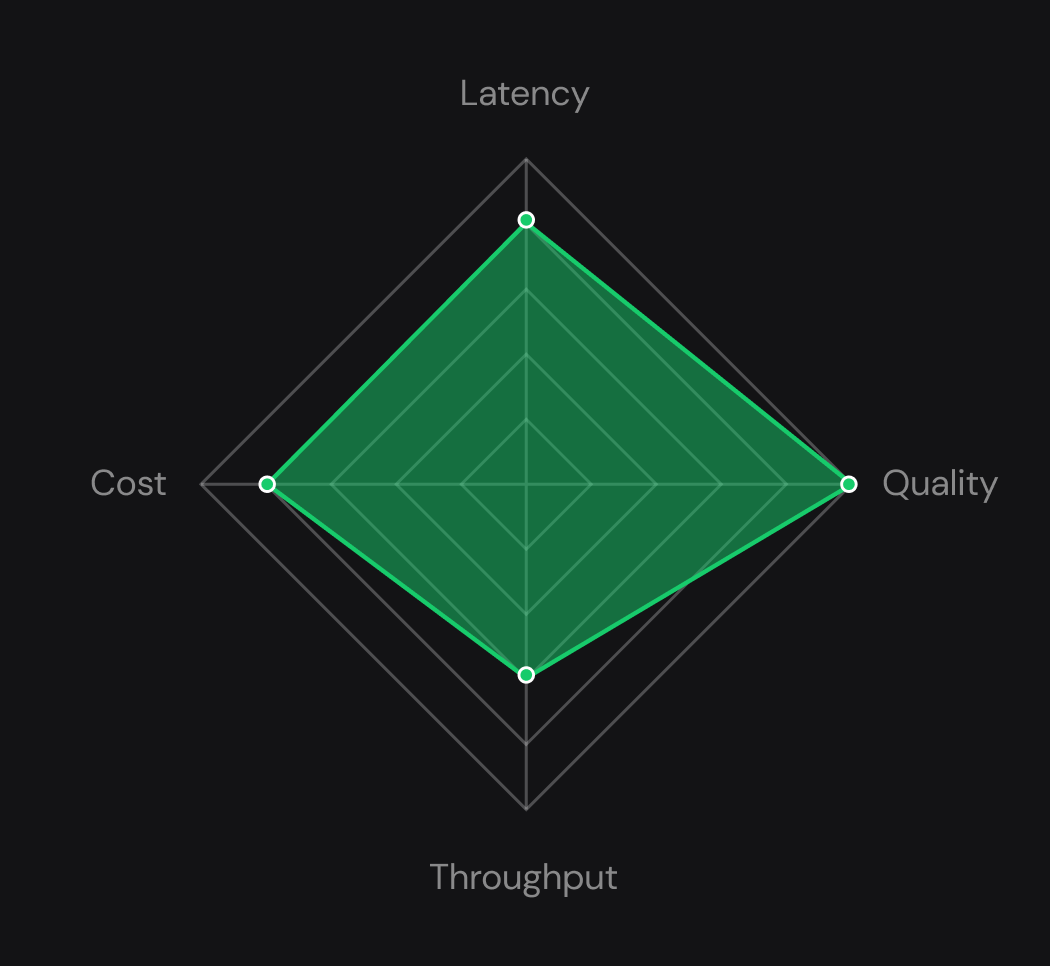
Dark-themed LLM inference configuration chart with hardware, frameworks, model backends, quantization, optimizations, KV caching, and a performance radar chart.
Green radar chart comparing latency, quality, throughput, and cost.
Real-time multi-agent reasoning
Content Generation
Real-time multi-agent reasoning
Optimised for Cost
Real-time multi-agent reasoning
Fine-tuned LLM
Real-time multi-agent reasoning
Scale based on usage
Hardware
Frameworks
Model Backend
Quantisation
Model Backend
Optimisations
KV Caching
T4
vLLM
Transformers
fp16
TP1
CUDA Kernels
Paged attention
A10G
Triton
vLLM Backend
FP8
TP2
Eagle
Static KV Cache
A100
LMDeploy
TensorRT
BF16
TP4
FA2
ShadowKV
H100
TensoRT LLM
ShadowKV
GPTQ
TP8
FA3
FB Cache
Dark-themed LLM inference configuration chart with highlighted hardware, frameworks, backends, quantization, optimizations, KV caching, and performance metrics.
Yellow radar chart comparing latency, quality, throughput, and cost.

Tested at Scale. Built for Production

Reliable deployments with 99.99% uptime, enterprise-grade security, and completely compliant with highest standards
GDPR
ISO 27001 v2022
AICPA SOC 2

Hear from our Partners

Don't take just our word for it, hear from companies that Simplismart has partnered with
"With Simplismart, we trained and deployed a vision model to process medical prescriptions at 95% accuracy. Their fine-tuning made inference fast, efficient, and effortlessly scalable"

Bhaskar Arun

Lead Data Scientist, Tata 1mg

"Running workloads at our scale demands both speed and adaptability. Simplismart delivered the fastest infrastructure we’ve used and stayed on top of every new development to keep us ahead.”

Ajay Dubey

Senior Engineering Manager, Mindtickle

"Simplismart’s optimizations cut our image generation costs from $30,000 to under $1,000 while halving inference time. Their solution integrated seamlessly, scaling effortlessly with our growing demand."

Shivam R.

Senior Director of Engineering, Invideo

"Simplismart’s solutioning helped us transition to custom models, and their fine-tuning expertise boosted our accuracy. The support quality has been outstanding and they handle all the MLOps heavy lifting so we can focus on building"

Elad Hirsch

Founding Research Scientist, Lica

"We had invested in GPUs, and Simplismart proved the best way to maximize them. Their optimizations cut our peak GPU usage from 15 to 6 while meeting latency targets, making our infrastructure faster and more cost-efficient"

Soumyadeep Mukherjee

Co-Founder & CTO, Dashtoon

Your AI Stack, Fully in Your Control

See how Simplismart’s platform delivers performance, control, and modularity in real-world deployments.
Built to Fit Seamlessly Into Your Stack

From GPUs to Clouds to Data Centers - Simplismart is engineered to integrate natively with your infrastructure and ecosystem partners.
Find out what is tailor-made inference for you.